Live on Google Cloud Run
MediQA Bot
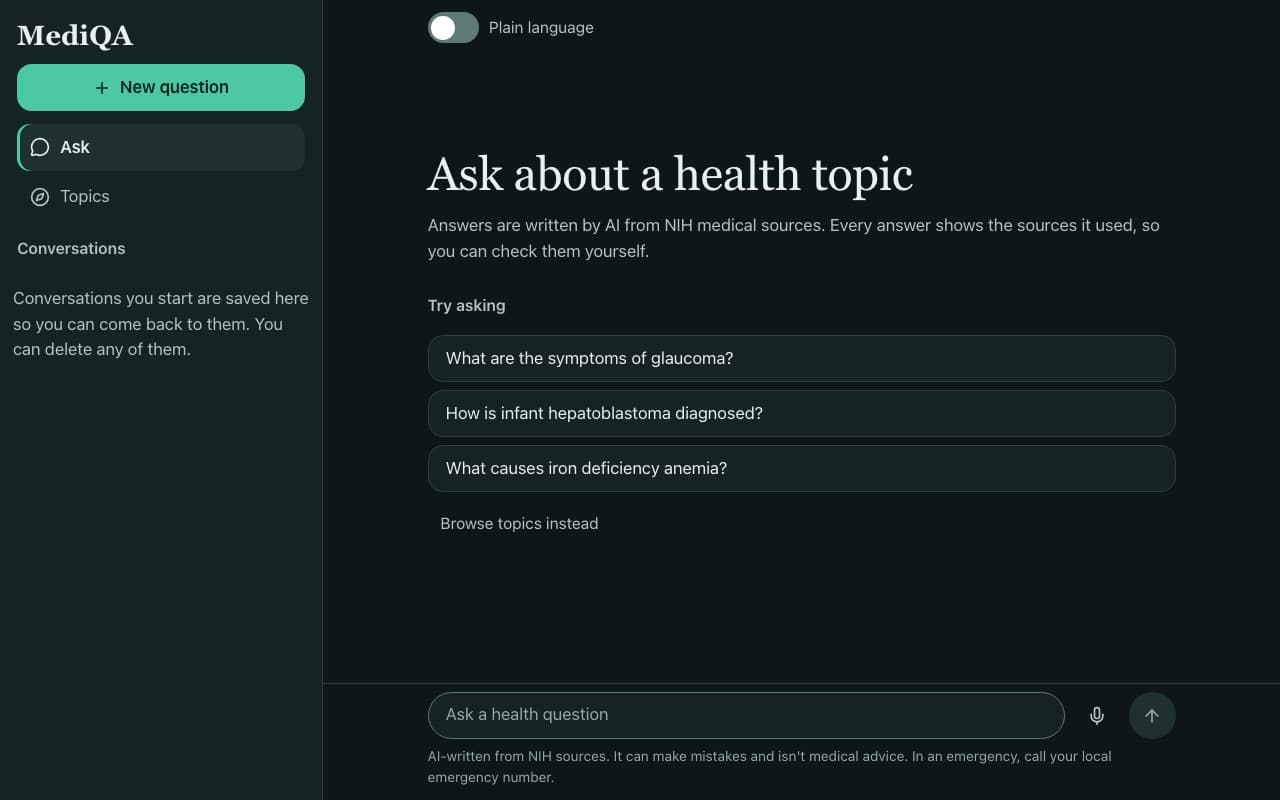
Medical Q&A that checks its own evidence.
The problem
A medical chatbot that answers confidently from weak evidence is worse than no chatbot. I wanted a system that notices when its retrieval is poor, tries again, and shows exactly what it used.
How it works
- QuestionA clinician asks a question in the React Progressive Web App.
- RetrieveDense PubMedBERT vectors and BM25 sparse vectors are searched together in Qdrant and fused with Reciprocal Rank Fusion.
- GradeA LangGraph node judges whether the passages answer the question.
- CorrectWeak evidence triggers a query rewrite and a second retrieval.
- AnswerThe reply cites its sources; Langfuse and PostgreSQL record the trace and cost.
Decisions
Hybrid retrieval
Dense vectors capture meaning. Sparse BM25 vectors catch exact clinical terms. Fusing both beats either alone.
ONNX embeddings
The embedding model is exported to ONNX and published, so the production image does not need PyTorch.
Cloud Run, not Spaces
Hugging Face Spaces needs a paid plan for Docker apps, so version 2 runs on Google Cloud Run.
Inspectable by design
Langfuse traces, PostgreSQL cost analytics and a retrieval-inspection view show what was fetched and why.